
An evaluation can go wrong before the model is trained. Transformations that learn from the dataset must respect the same training boundary as the estimator.
Scikit-learn pipelines combine preprocessing and estimation steps into a single workflow. Scikit-learn — compose.
Identify learned steps
For a product-record model, scaling statistics or selected features may depend on training data. Fitting them on the entire dataset first can expose the evaluation subset indirectly. Treat those steps as part of model development.
Preserve the sequence
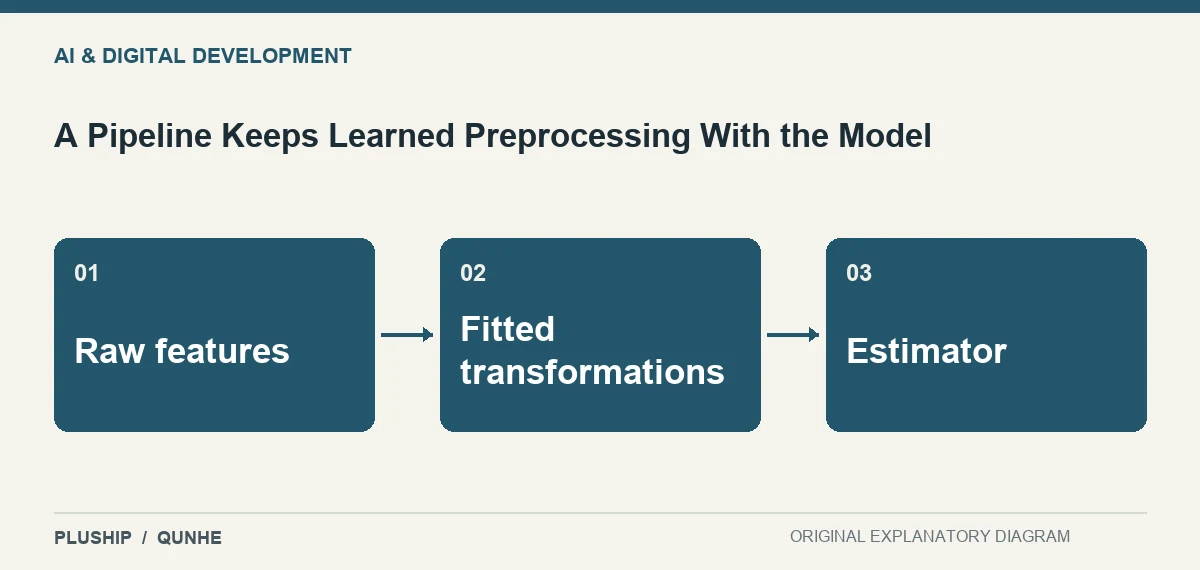
Keep the fitted transformations and their order with the trained estimator. Rebuilding only the final predictor with different preprocessing can change results. A pipeline makes the intended relationship clearer, while the actual data and implementation still require verification.

Source reviewed 25 October 2026. Interpretation and original diagrams: PLUSHIP / Qunhe. Examples are illustrative.
Related reading
Resizing Can Change the Shape a Vision Model Sees
Feature Selection Changes Which Inputs a Model Can Use